Objective
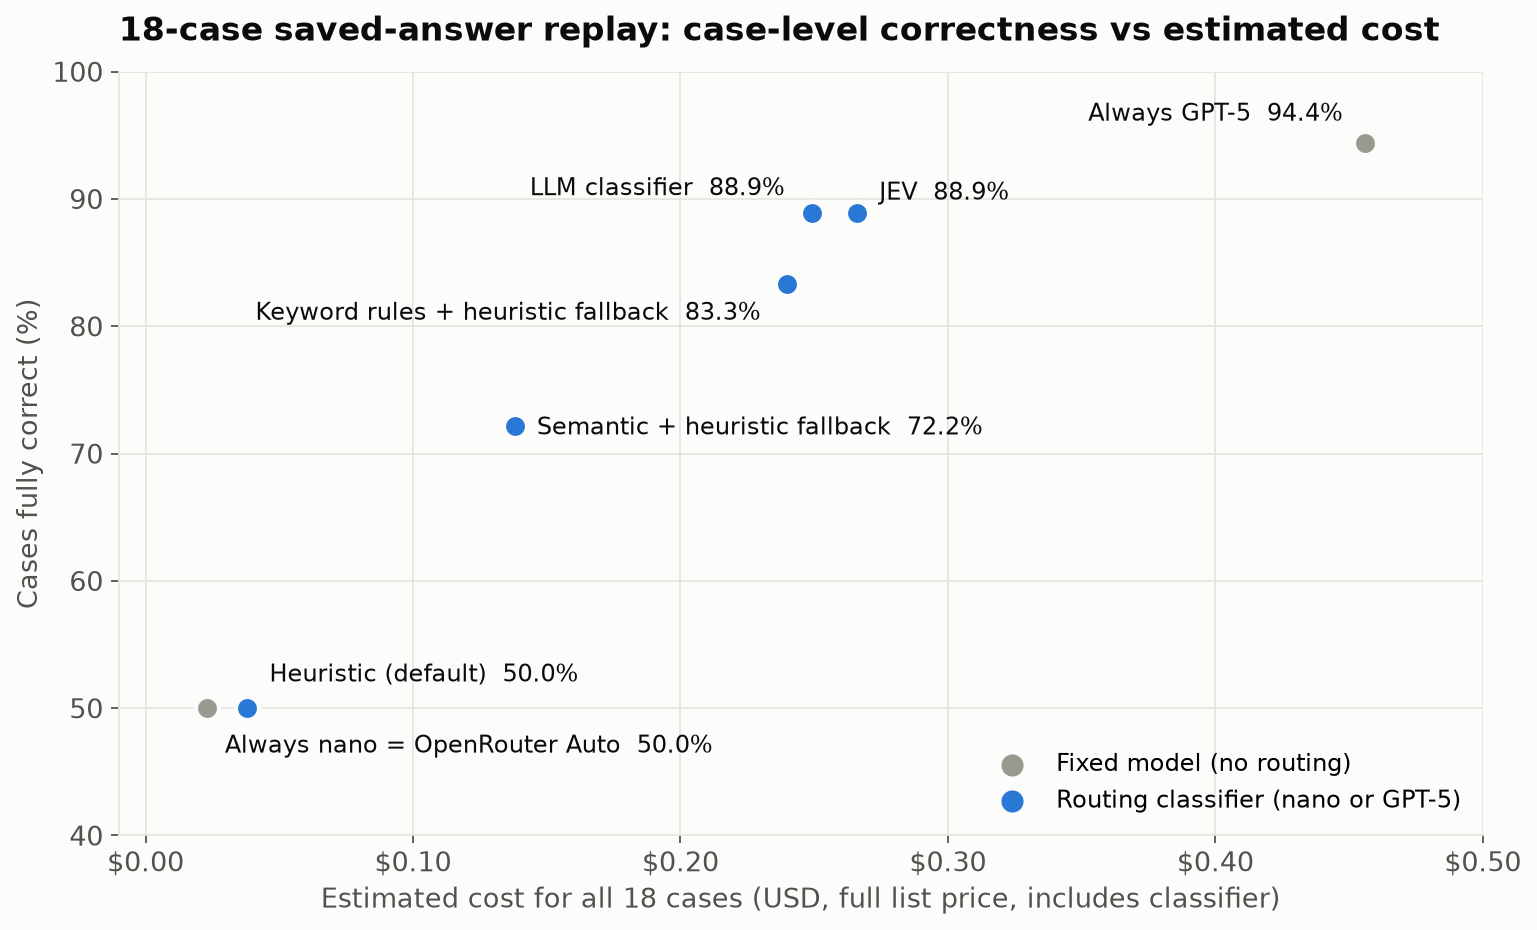
In Part 1, I compared ways to choose which model should answer a support request. This post continues that experiment with a second decision: how long should that model choice last—a whole conversation or just one question? The small pilot illustrates a method, not a general recommendation.
I compared four policies on six new three-question conversations: always GPT-5 nano, always GPT-5, per-conversation routing and per-question routing. Nano and both routing policies got 4 of 6 conversations fully correct; GPT-5 got all six. Routing cost about nine times nano, without improving the fully-correct-conversation count. Neither scope clearly won.
The Agent and Classifier
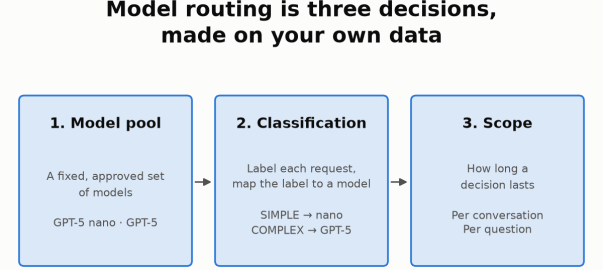
The agent answers marketplace support questions using read-only SQL and policy search, through the OpenAI Agents SDK and LiteLLM, with Langfuse tracing. Part 1 compared classifiers on 18 cases. Here I reuse its domain-aware nano classifier: SIMPLE → nano, COMPLEX → GPT-5.
My Starting Expectation
I expected per-conversation routing to preserve context and cache warmth, while per-question routing could save money on easy follow-ups. I also assumed switching would lose context or start cold. These were assumptions to test, not established properties.
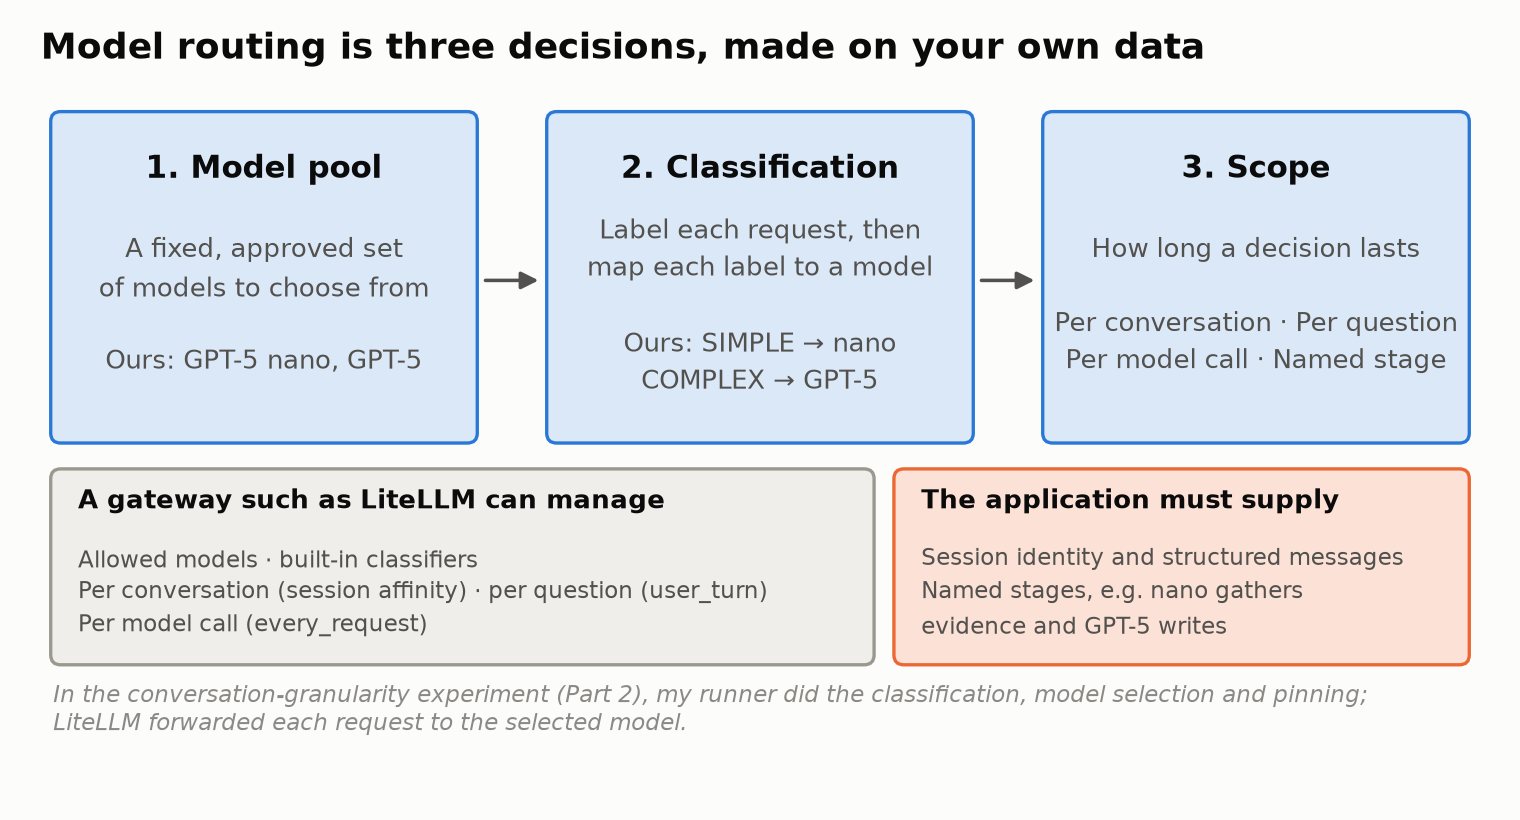
Ways to Scope a Routing Decision
A gateway can manage most of these for you. LiteLLM’s documentation describes three built-in options:
- Per conversation: session affinity pins the model chosen on the first turn of a session and skips reclassification on later turns.
- Per question:
classification_mode: user_turnclassifies only new user questions, and carries that decision through the tool calls and continuation turns within the question. - Per model call:
classification_mode: every_request(the default) classifies each request the agent sends to the gateway.
For any of these to work, the application supplies the session identity (LiteLLM reads a session_id from the request metadata) and well-structured messages, so the gateway can tell a new user question from a tool result.
Two more options need the application’s knowledge:
- Named stages: a deliberate rule such as “nano gathers the evidence, GPT-5 writes the final answer”. The gateway can reclassify every call, but only the application knows which call is “gathering” and which is “writing”.
- Escalation: start on nano and switch up when a check fails. This needs a reliable signal that an answer is wrong.
Here is what a single question looks like inside the agent:
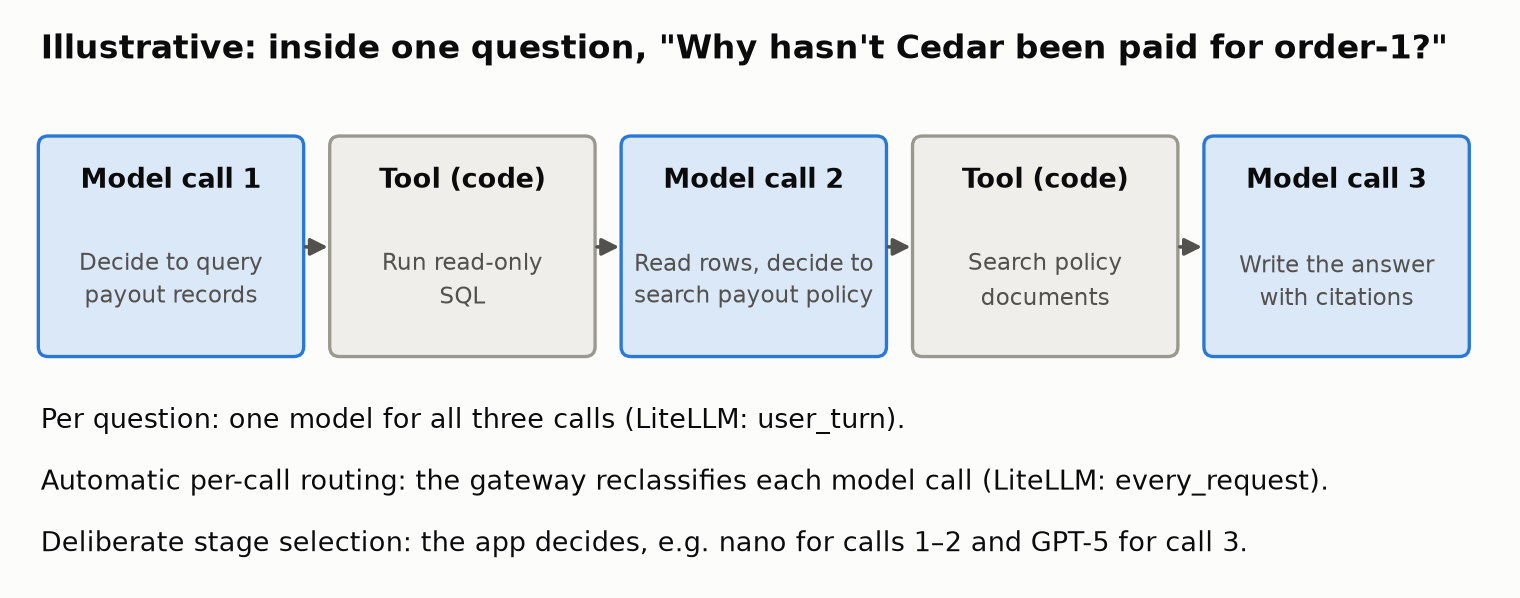
I tested per conversation and per question, against the two fixed models.
How I Tested It
What I implemented. My own runner did the classification, the model selection and the pinning. LiteLLM simply forwarded each request to the model the runner had explicitly selected. So these results test the two routing policies, not LiteLLM’s native session-affinity or user_turn implementations. Every internal model call for a question used the model chosen for that question.
The conversations. I wrote 6 new conversation scenarios of 3 questions each, with expected answers written in advance. They cover:
- simple questions leading to hard ones, and the reverse
- a clarification
- a purchase that changes the data mid-conversation
- a clock change that lets a payout hold pass
- simple lookups only
The policies. Each scenario ran once under four policies:
- always nano
- always GPT-5
- per-conversation routing
- per-question routing, where the classifier also sees the earlier conversation
Six scenarios × three questions × four policies is 72 answers, but only 6 distinct scenarios, not 72 independent tests. I couldn’t reuse saved answers as in Part 1, because each answer shapes the next question’s context.
Grading. An LLM reviewer, GPT-6 Astra, reviewed every answer against the expected facts, and I adjudicated the borderline cases. Three borderline partial grades were flagged; I reviewed and accepted them. A conversation counts as fully correct only if all three of its answers are correct, because a support conversation with one bad answer is still a failed conversation.
One Conversation, Two Scopes
Here is one scenario, “simple lookup to payout investigation”, under the two routing policies:
| # | Question | Per conversation | Per question |
|---|---|---|---|
| 1 | “For order-2, list the purchased product, quantity and seller.” | nano (pinned for the conversation) ✅ | nano ✅ |
| 2 | “For that same order, explain why its seller has not received the payout and what must happen before release.” | nano ⚠️ partial | GPT-5 ✅ |
| 3 | “What exact amount is currently payable to that seller for this order, after the marketplace fee?” | nano ✅ ₹1,618.20 | GPT-5 ✅ ₹1,618.20 |
The first question looked simple, so per-conversation routing pinned the whole conversation to nano, including the harder second question. Per-question routing classified question 2 as COMPLEX and sent it to GPT-5. The classifier’s reason: “Determining why a seller payout is not completed requires tracing allocations, payments, shipments, returns/refunds, and payout status, plus policy-based eligibility.”
The Results
The headline measure is conversations with all three answers correct. Costs are cache-adjusted usage estimates for these newly generated answers. They are reconstructed from the token and cached-token counts the provider reported, at fixed list rates.
| Policy | Conversations fully correct | Cache-adjusted usage estimate, 6 conversations | vs always GPT-5 |
|---|---|---|---|
| Always nano | 4 / 6 | $0.014 | −94.9% |
| Always GPT-5 | 6 / 6 | $0.271 | — |
| Per conversation | 4 / 6 | $0.126 | −53.4% |
| Per question | 4 / 6 | $0.127 | −53.2% |
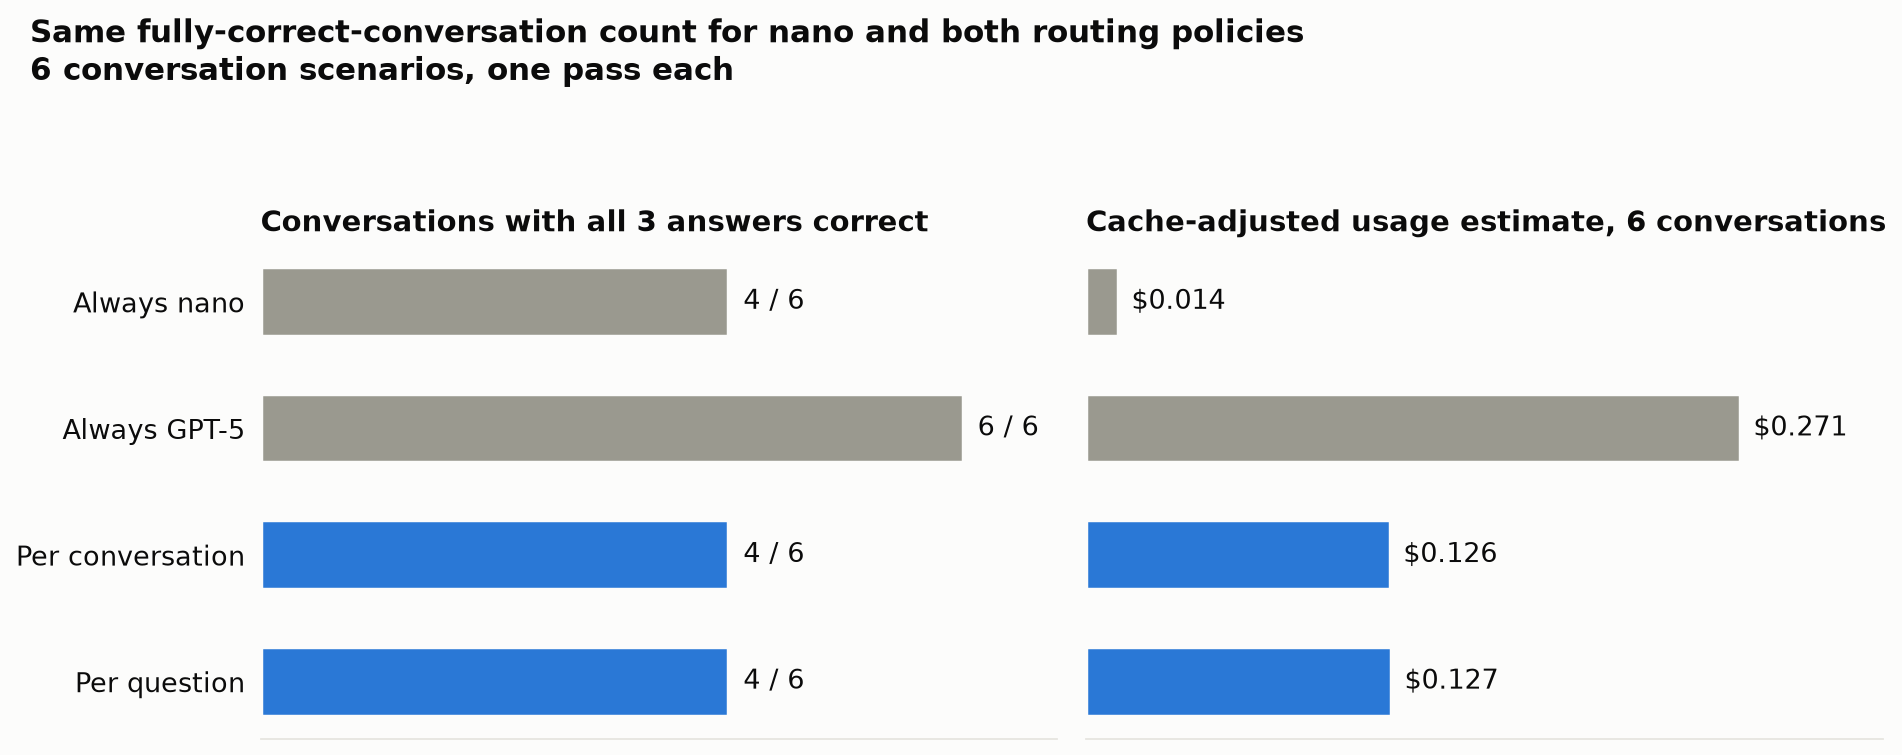
- Nano and both routing policies each got 4 of 6 conversations fully correct; GPT-5 got 6 of 6.
- Routing cost about nine times nano, and it did not improve the fully-correct-conversation count.
- Routing did reduce incorrect individual answers. Out of 18 answers per policy, nano got 15 correct, 1 partial and 2 incorrect; both routing policies got 15 / 2 / 1. Fewer wrong answers did not produce more fully correct conversations.
- Neither granularity established a compelling advantage. Per conversation and per question got the same conversation score at almost the same cost.
Both routing policies chose nano for 12 of the 18 questions and GPT-5 for 6, though not always the same questions. Per-question routing switched models four times across the six conversations.
Right vs Wrong: Two Conversations in Detail
1. Per-question routing caught the harder question. In the scenario above, question 2 asks why the seller hasn’t been paid. The correct answer is that payment is captured, the shipment is still pending, and the payout is held until delivery is confirmed and a 24-hour hold has passed.
- Per-conversation routing (pinned to nano): said the payout “is currently held” until “delivery/fulfillment conditions are satisfied”. It left out the 24-hour hold, so it was graded partial.
- Per-question routing (sent to GPT-5): “Policy requires delivery confirmation plus a 24-hour hold… No delivery confirmation is recorded yet.” Correct.
Routing the hard question to the stronger model helped here. But there is a twist: in the separate always-nano run, nano answered this same question correctly. Same model, same question, different run, different grade. One run is not proof.
2. When every question looks simple, no scope helps. This scenario was about a name that means two things: “Cedar” is both a seller (Cedar & Co.) and a product (Cedar Desk).
- “Please list purchases associated with Cedar.” Nano correctly asked whether I meant the seller or the product.
- “The seller Cedar & Co., not the desk product.” Nano invented a “today only” date filter nobody asked for and replied that there were no purchases. In fact there was one: order-1, with two Canvas Weekenders. Graded incorrect.
- “Within those purchases, show only items that have not been delivered.” Nano answered “none”. That happens to be the right result, since the order had been delivered, but only because the previous answer had filtered everything out. Right answer, wrong reason, graded partial.
The classifier labeled all three questions SIMPLE, and on the surface they are: a list, a clarification, a filter. So both routing policies used nano throughout and made the same mistakes. GPT-5 alone got all three right. Per-question routing only helps if the classifier can tell that a question is risky, and follow-ups often look simpler than they are. Once a wrong answer enters the conversation, later answers build on it.
What It Costs
The pilot also recorded latency and caching. Full-price estimates are shown next to the cache-adjusted estimates so the effect of caching is visible.
| Policy | Cache-adjusted estimate | Full-price estimate | Cached share of input | Latency p50 / p95 | Model switches |
|---|---|---|---|---|---|
| Always nano | $0.014 | $0.020 | 50.6% | 10.3 s / 20.2 s | 0 |
| Always GPT-5 | $0.271 | $0.460 | 64.0% | 13.2 s / 34.8 s | 0 |
| Per conversation | $0.126 | $0.206 | 54.0% | 10.4 s / 33.1 s | 0 |
| Per question | $0.127 | $0.219 | 57.9% | 13.4 s / 38.8 s | 4 |
- Caching changes the estimate a lot. For always-GPT-5, the cache-adjusted usage estimate was about 40% below the full-price estimate. Neither figure is an invoice.
- Report cache differences, don’t explain them away. Per-question routing switched models four times, and its cached share was 57.9% against 54.0% for per-conversation. I am not attributing that difference to model switching, or to anything else, because two things make it hard to interpret:
- Provider caches were shared and could already be warm across runs.
- One conversation was interrupted mid-run when my API credit ran out. It resumed after funding, which may have changed cache warmth.
- Treat the latency figures as rough. p95 over 18 answers per policy is an indicator, not a production estimate.
What Happened to My Expectation
I expected per-conversation routing to win on context and caching, with per-question routing trading some of both for lower cost. Here is how each part held up:
- Context: my assumption was wrong. A model switch doesn’t lose the conversation. The application passes the conversation history with every call, so the model answering question 2 sees question 1 and its answer, whichever model it is. What carries over from one question to the next is the content of earlier answers, including their mistakes, not the model.
- Caching: I didn’t observe the penalty I expected. The per-question policy’s cached share was higher, not lower, and that held within each model too: nano 51.5% versus 47.8%, GPT-5 66.9% versus 61.6%. With shared cache warmth, the funding interruption and a single pass, this observation doesn’t tell me why.
- Cost: effectively the same. $0.126 for per-conversation, $0.127 for per-question.
- Accuracy: the same conversation score, with different mistakes. Per-question routing rescued one question the pinned conversation got partly wrong. In another conversation, neither scope helped, because every question looked simple.
So the pilot didn’t confirm my expectation, and it didn’t reverse it either. It was inconclusive. The useful part is seeing that the differences between the scopes were smaller and more situational than I assumed.
Pros and Cons of Each Scope
No scope is best in general. Each one trades something:
| Scope | Pros | Cons | Consider it when |
|---|---|---|---|
| Per conversation | One classification per conversation; one model; simplest to run and explain | The first question decides for all later ones; a simple opener can leave a hard follow-up on nano | Conversations tend to stay at one level of difficulty |
| Per question | Adapts when a conversation gets harder or easier; conversation history still carries over | A classification on every question; follow-ups often look simpler than they are; more model switches to monitor | Conversations often mix quick lookups with investigations |
| Per model call (automatic) | The gateway can reclassify every call with no application changes | Calls within one question may land on different models; more classifications; the classifier sees the call, not the stage | You want fine-grained routing without writing stage logic |
| Named stages (application-defined) | Can reserve the stronger model for the stage that needs it, such as writing the final answer | The application must identify the stages; the final stage often carries the most context, so it may not save much | Failures cluster in one stage, such as interpreting evidence |
| Escalation | Pays for the stronger model only when the cheaper one fails | Needs a reliable signal that an answer is wrong; fluent wrong answers slip through; slower when it escalates | You have strong automatic checks on answers |
A Checklist for Choosing Routing
Steps 1–4 are from Part 1; steps 5 and 6 come from this post.
- Shortlist models on benchmarks, domain fit, cost and latency, from approved providers that support your agent’s needs.
- Run evals on your golden set, with single questions and full conversations, to narrow the shortlist. Then fix the pool and pin the versions.
- Weigh cost savings against accuracy. If the cheaper model meets your accuracy bar, use it. If only the stronger one does and its cost is acceptable, use it. Route only when routing saves meaningful cost while keeping accuracy within your bar.
- Design the classification. Choose labels that matter for your traffic and map them to models. Start with keyword rules, then try semantic or LLM-based classifiers built from real user journeys.
- Choose the granularity on real conversations. Compare per conversation and per question (and per call or named stages if they fit your agent) on multi-question conversations, watching conversation-level correctness, cost, latency and caching.
- Validate and monitor. Re-test on fresh scenarios and repeat unstable cases before deciding, and rerun your evals whenever a model changes or retires.
Limits and What’s Next
This was a small pilot, and I would not treat it as a benchmark:
- Sample size: 6 conversation scenarios of 3 questions, one pass per policy.
- Grading: an LLM reviewer plus my adjudication of borderline cases.
- Classifier: a prompt developed on known cases.
- Implementation: my own runner, not the gateway’s native routing.
- Caching: shared cache warmth and a funding interruption; the figures are observations, not causal proof.
The “different run, different grade” twist above shows how much one pass can vary. Next, I want to:
- run more conversations, with repeated passes
- repeat the test with LiteLLM’s native session affinity and
user_turn - try named-stage routing, with nano gathering evidence and GPT-5 writing the answer
- test escalation, once I have a reliable signal that an answer is wrong
- run controlled cache tests
Acknowledgements
This post was written with the help of Claude Opus 5.5 in Claude Code, which also helped me research the routing landscape and plan the experiments. The application and experiments were built and run with GPT-6 Astra, which also reviewed answers against the expected results.
References
This Series
- Model Routing, Part 1: Choosing a Classifier: the model pool, grading, and six classifiers compared on 18 support cases.
Earlier Posts
- Right Model, Right Job: A Daily AI Digest with Jev and Claude at 1/10th the Cost: using the right model for each step of a workflow.
Routing Tools
- LiteLLM Auto Routing: session affinity,
classification_mode(every_requestanduser_turn) and classifier configuration.